November 18
You’re in alpha testing. Users are coming. Bugs are surfacing. Every bug feels urgent because external people will see it. The reactive instinct is powerful: see bug, fix bug, push fix, move on. It feels productive. It feels responsive. It feels like you’re solving problems quickly.
But sometimes the fastest way to fix bugs is to stop fixing bugs and start thinking systematically.
That’s the choice we faced on a Monday morning, and choosing systematic — even when reactive felt faster — made all the difference.
The reactive pattern
Monday started with alpha testing validation. I was testing the Quick Start guide on a fresh laptop, experiencing Piper Morgan the way an external alpha tester would. Clean environment, following documentation exactly, no customizations from months of development.
Issues surfaced immediately:
- pip install failing (Python version mismatch)
- Documentation regressions (instructions unclear)
- Port check reporting incorrectly (TIME_WAIT socket state bug)
- Database migrations invisible (no progress feedback)
- Keychain checks silent (no indication of what’s happening)
- Username conflicts when setup fails midway
- Status command throwing exceptions (three separate bugs)
- Documentation links broken (five dead links)
By noon, we had a list. Eight distinct problems. Each one preventing a smooth alpha testing experience.
The reactive approach would be: tackle them in order. Fix pip install. Push. Fix port check. Push. Fix migrations visibility. Push. Keep going until the list is done. Ship incrementally. Get fixes into users’ hands quickly.
This approach has benefits. It’s fast. Users see progress. Each fix lands quickly. If you hit a blocker, you’ve already shipped some improvements. Incremental value delivery.
But reactive fixing has hidden costs. Each fix is isolated, made without understanding patterns across bugs. Related issues get fixed at different times with different approaches. You miss opportunities to address root causes. Technical debt accumulates from quick fixes that don’t consider the larger system.
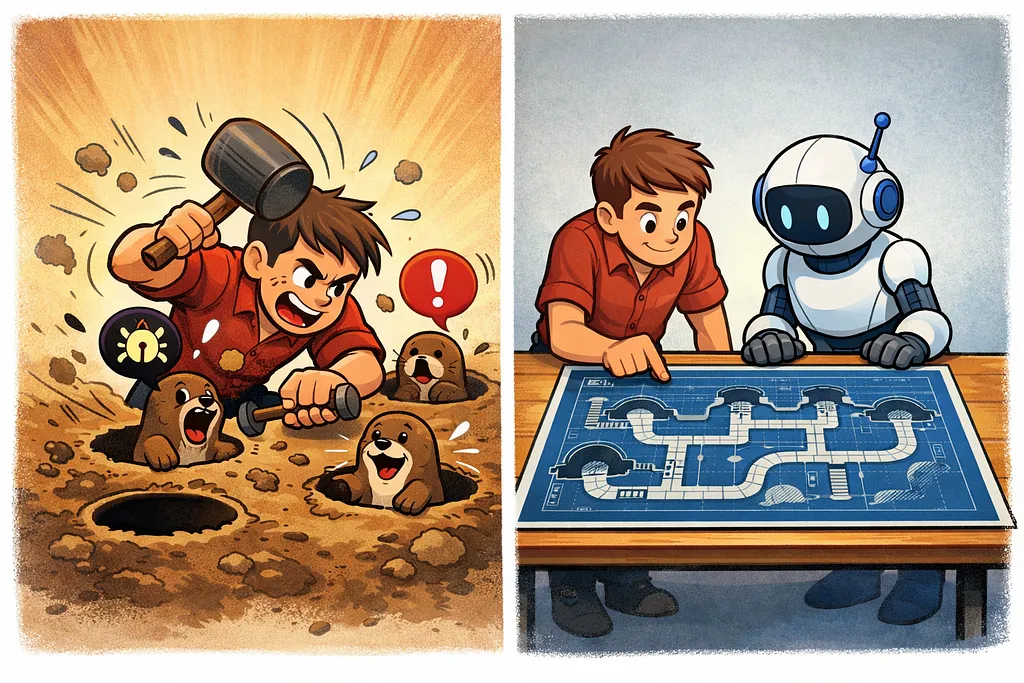
It’s seductive and easy to slip into. I had to rely on my spidey-sense to remind me that I was slipping back into the unstructured vibe coding approach that lead to whack-a-mole.
The systematic intervention
At 1:45 PM, I gave feedback that changed the approach: “Stop piecemeal fixes, need systematic plan.”
We’d been heading toward reactive patching. See bug, fix bug, push fix. But the bugs weren’t random. They were revealing patterns:
- Visibility pattern: Multiple operations happening silently (migrations, keychain checks)
- Error handling pattern: Exceptions without user-friendly messages
- State management pattern: Incomplete setups leaving orphaned data
- Documentation pattern: Links broken, instructions unclear
These weren’t eight separate problems. They were manifestations of a few systemic issues: insufficient user feedback, incomplete error handling, missing cleanup logic, documentation drift.
The systematic approach: stop, analyze patterns, group related issues, create comprehensive plan, execute phases methodically.
This felt slower. Reactive fixing could start immediately. Systematic planning required time upfront. But the systematic approach addresses root causes, not just symptoms.
The five-phase plan
By 5:05 PM, my Code Agent had created a comprehensive five-phase plan:
Phase 1: Database Migrations (alembic visibility)
Not just “make migrations work” but “make migrations visible, automatic, and informative.” Run alembic with proper working directory. Show progress messages. Handle user_api_keys migration cleanly. The visibility pattern addressed systematically.
Phase 2: Keychain Check Visibility (progress feedback)
All three providers (OpenAI, Anthropic, GitHub) get consistent progress feedback. “Checking keychain for existing key…” messages. Success/failure indicators. Exception handling with clear error types. The visibility pattern again, but now established as standard practice.
Phase 3: Username Reclaim (incomplete setup handling)
When setup fails midway, allow username reclaim. Ask user if they want to resume or delete incomplete account. Show progress during cleanup. Graceful error handling. The state management pattern systematically addressed.
Phase 4: Status Command Bugs (three fixes grouped)
Fix dict access pattern (key.is_active → key[“is_active”]). Add missing fields. Fix timestamp parsing. Eliminate duplicate logging. Three related bugs fixed together with consistent approach. The error handling pattern systematically addressed.
Phase 5: Polish (documentation and guards)
SQLAlchemy import guard with helpful error message. Fix five broken doc links. Comprehensive cleanup. The documentation pattern systematically addressed.
Five phases. All related issues grouped. Each phase addresses patterns, not just individual bugs. Execution time: 115 minutes total.
Compare to reactive: fixing eight bugs individually might take 30 minutes. But you’d fix the symptom each time, not the pattern. You’d add progress feedback to migrations but not to keychain checks (because they’re “different”). You’d fix one status command bug but miss the other two (because you’re moving fast). You’d patch one doc link but not audit the rest (because the immediate pain is resolved).
The systematic approach cost 85 extra minutes but delivered comprehensive solutions to systemic problems. That’s the time investment in systematic thinking.
When systematic beats reactive
Not every situation needs systematic intervention. Sometimes reactive is exactly right. The question is knowing when to stop and think systematically.
Choose systematic when:
Multiple bugs share patterns or root causes. If three bugs all stem from insufficient user feedback, fixing them individually wastes the opportunity to establish consistent feedback patterns.
You’re preparing for external users or stakeholders. First impressions matter. Shipping partially-fixed systems creates “it’s rough around the edges” perception. Systematic fixes demonstrate thoroughness.
Technical debt is already high. Reactive fixes on top of technical debt compound the problem. Systematic approaches can clean up debt while fixing bugs.
The system is about to scale. Patterns matter more at scale. Systematic fixes establish patterns that scale. Reactive fixes create inconsistencies that multiply.
You’re feeling overwhelmed by issue volume. Counterintuitively, when bugs feel overwhelming, systematic approaches reduce cognitive load. Group related issues, tackle patterns, reduce problem space.
Choose reactive when:
Issues are truly independent. If bugs don’t share patterns or root causes, reactive fixes are efficient.
You need immediate mitigation. Critical bugs blocking users need quick fixes first, systematic improvements later.
You have perfect information. If the problem is completely understood and isolated, systematic planning is overkill.
Resources are extremely limited. Sometimes you only have time for quick fixes. Systematic is better but not always available.
The key insight: systematic costs time upfront but saves time downstream. Reactive ships faster but creates maintenance burden. Choose based on whether you’re optimizing for immediate delivery or sustainable quality.
The discipline under pressure
Here’s what makes systematic hard: it requires stopping when momentum says go.
Monday morning, bugs were surfacing. External alpha testers were coming. Every instinct said: fix things fast, ship incremental improvements, keep moving. Stopping to analyze patterns and create comprehensive plans felt like delay.
But that’s exactly when systematic thinking matters most. When pressure is highest, the temptation to react rather than think is strongest. And that’s when reactive approaches create the most future problems.
The discipline is: stop anyway. Analyze anyway. Plan anyway. Even when it feels slow. Even when the deadline looms. Even when reactive seems faster.
Because systematic only feels slower. In reality:
Reactive approach:
- 30 minutes: Fix 8 bugs individually
- 2 hours: Debug new issues from inconsistent fixes
- 1 hour: Document the inconsistencies
- 3 hours: Refactor later to establish patterns
- Total: 6.5 hours, with breaks in workflow
Systematic approach:
- 1 hour: Analyze patterns and create plan
- 2 hours: Execute five phases comprehensively
- 15 minutes: Document completed work
- Total: 3.25 hours, continuous workflow
The systematic approach costs more upfront. But it eliminates future work. No debugging inconsistent fixes. No refactoring later. No accumulating technical debt. The time is invested once, properly, then you’re done.
What systematic actually means
Systematic doesn’t mean slow or bureaucratic or over-engineered. It means:
- Pattern recognition — Seeing that multiple issues share root causes
- Strategic grouping — Organizing fixes around patterns, not symptoms
- Comprehensive execution — Addressing all instances of a pattern together
- Consistent approaches — Establishing standards through systematic fixes
- Complete documentation — Recording what was learned for future work
The five-phase plan executed Monday wasn’t bureaucratic. It was efficient. Instead of context-switching between eight separate bugs, we tackled related bugs together. Instead of fixing symptoms repeatedly, we addressed patterns once.
Systematic means thinking strategically about problems before implementing solutions tactically. It means investing time in understanding before spending time in fixing. It means building solutions that prevent future problems, not just solving current ones.
This is what “work smarter, not harder” actually looks like in practice. Working harder would be fixing eight bugs individually as fast as possible. Working smarter is recognizing the patterns, grouping the fixes, and solving problems systematically in less total time.
The alpha testing outcome
By 6:45 PM, all five phases were complete. The wizard was functional. Test user successfully created. Setup experience smooth. Progress feedback throughout. Error handling comprehensive. Documentation updated.
We shipped to alpha testing with systematically-solved problems, not reactively-patched symptoms.
The difference showed. When issues surfaced during testing, they were new issues, not variations of partially-fixed old issues. The systematic approach eliminated entire categories of problems. Reactive fixing would have eliminated specific instances.
That’s what systematic buys: comprehensiveness. You don’t just fix the bug you saw. You fix all the bugs with that pattern, including the ones you haven’t seen yet.
Alpha testing continues. But it’s testing a systematically-hardened system, not a reactively-patched one. That difference matters for first impressions, user confidence, and long-term quality.
The temptation to react will return. It always does. More bugs will surface. The pressure to fix quickly will be real.
But we’ve learned: systematic beats reactive. Even when it feels slower. Even when pressure is high. Even when momentum says keep moving.
Sometimes the fastest way to fix bugs is to stop fixing bugs and start thinking systematically about what’s actually wrong and how to fix it properly.
That’s the discipline. That’s the choice. That’s what systematic means.